PrecepTron
An open LLM judge for scalable, physician-level evaluation of clinical reasoning.

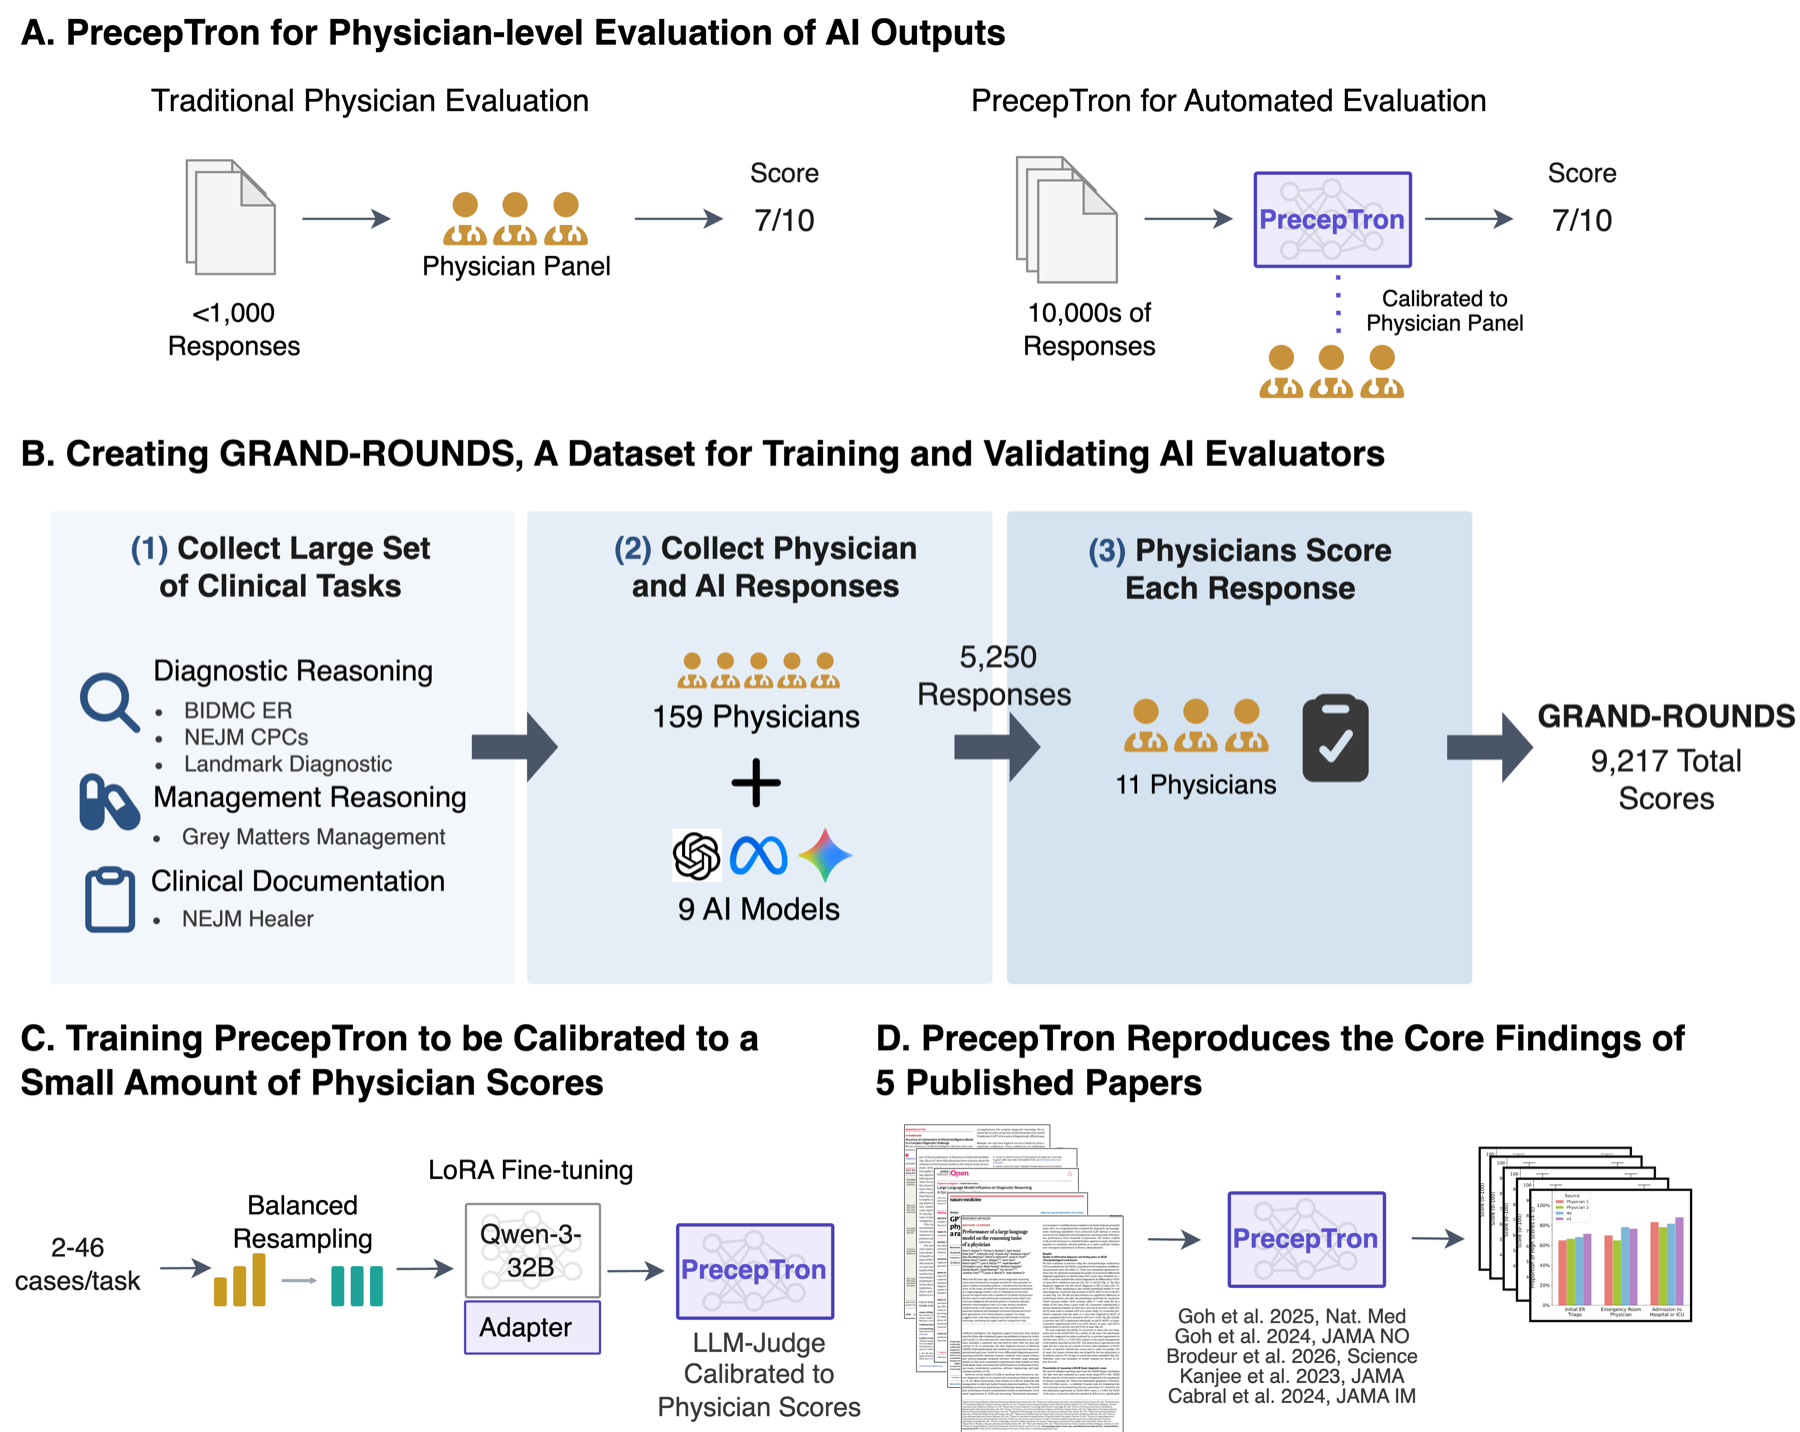
PrecepTron is a fine-tuned 32B model that grades open-ended clinical reasoning against validated rubrics, calibrated to a physician panel from only a handful of scored examples per task. It is small enough to run on local hospital infrastructure, reaches physician-level agreement, and lets researchers evaluate clinical LLM outputs at a scale that manual physician grading cannot reach.
To develop and validate it, we built GRAND-ROUNDS, a benchmark of 9,217 physician scores across 5,250 open-ended clinical responses — spanning diagnostic reasoning, management, and clinical documentation — drawn from seven published studies and graded by 11 physicians. The public release contains all of GRAND-ROUNDS except the BIDMC emergency-department task, which contains protected health information.
Resources
- 🤗 Models & dataset on Hugging Face — the PrecepTron-32B judges and the GRAND-ROUNDS benchmark.
- 📊 GRAND-ROUNDS dataset
- 📋 Task rubrics
- 💻 Code on GitHub
- 📄 Paper (arXiv) — Scaling Clinical Judgment to Evaluate Medical AI.
Citation
@article{buckley2026preceptron,
  title   = {Scaling Clinical Judgment to Evaluate Medical AI},
  author  = {Buckley, Thomas A. and Kanjee, Zahir and Brodeur, Peter G. and
             Crowe, Byron and Pettinato, Anthony M. and Shah, Aashna P. and
             Haimovich, Adrian D. and McCoy, Liam G. and Restrepo, Daniel and
             Freed, Jason A. and Goh, Ethan and Chen, Jonathan H. and Zwaan, Laura and
             Goodman, Katherine E. and Morgan, Daniel J. and
             Abdulnour, Raja-Elie E. and Rodman, Adam and Manrai, Arjun K.},
  year    = {2026},
  journal = {arXiv preprint arXiv:2609.12822},
  url     = {https://arxiv.org/abs/2609.12822}
}